
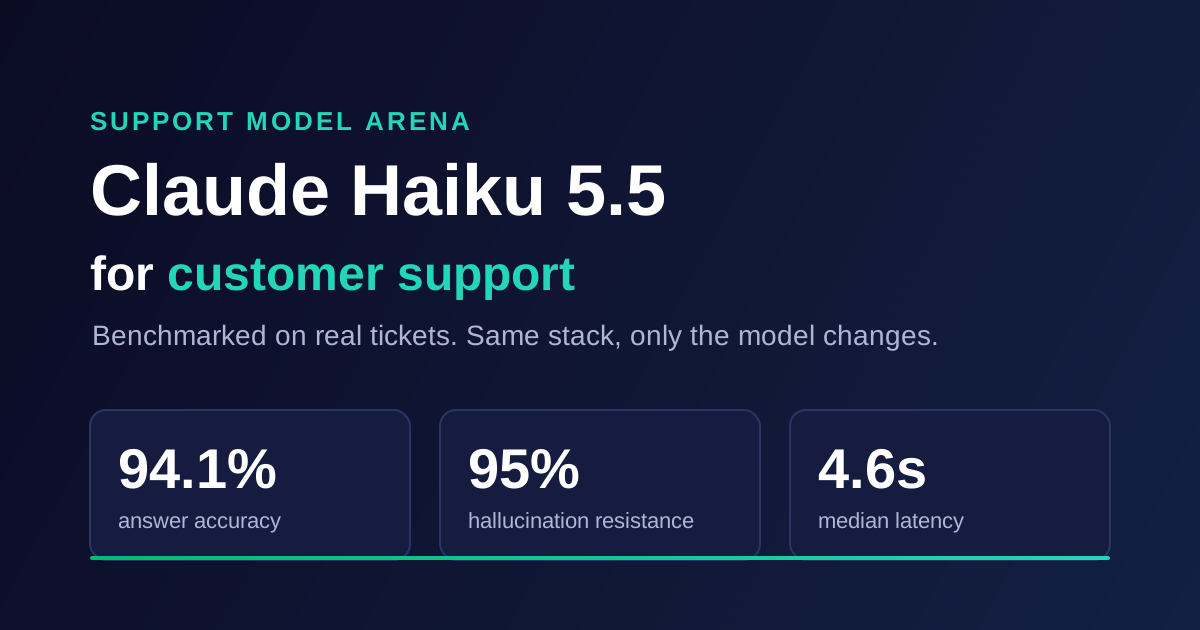
Claude Haiku 5.5 for Customer Support: Benchmark Results
IrisAgent now supports Claude Haiku 5.5, Anthropic's newest small model. We ran it through the same customer-support suites we use for every model on the Support Model Arena. The short verdict: at $0.10 per million input tokens, it is the best all-round support model at its price point, it is fast with a tight latency tail, and it declines instead of guessing far more reliably than the Haiku generation before it. It is not the model we would pick for ticket tagging or complex intent routing.
The short version
Overall score 90.7%, the highest of any model priced at $0.10 / $0.50 per million tokens on our board.
95% hallucination resistance on tickets that must not be answered from the knowledge base. The high-effort variant reached 100%.
94.1% answer accuracy on real, answerable support tickets.
4.6 second median latency and a 9.5 second p99, one of the tightest tails among low-cost models.
Weakest at ticket tagging (84.7%) and cited sources (77.6%), where larger models and some same-price peers do better.
How we tested
Every model on the arena runs inside the same production IrisAgent stack. Same retrieval, same tools, same prompts. Only the model changes. We grade five support jobs:
Answer accuracy: anonymized real support tickets whose answer exists in the knowledge base. A pass is a correct, grounded resolution.
Hallucination resistance: tickets that must not be answered from the knowledge base. A pass is a decline or handoff instead of an invented answer.
Cited sources: the same answerable tickets, but the answer must also cite the right knowledge base article.
Intent routing: multi-turn chats routed against configured FAQ intents and workflows, including near-miss intents and escalation requests.
Ticket tagging: exact-match classification across three production tag catalogs from B2B customers.
The Overall score weights these 30% answer accuracy, 30% hallucination resistance, 15% cited sources, 15% intent routing and 10% tagging. The full method and every other model are on the Support Model Arena.
Results
Model | Overall | Answer accuracy | Hallucination resistance | Cited sources | Intent routing | Ticket tagging | Median latency | Price per 1M tokens (in / out) |
|---|---|---|---|---|---|---|---|---|
Claude Haiku 5.5 | 90.7% | 94.1% | 95.0% | 77.6% | 92.5% | 84.7% | 4.6s | $0.10 / $0.50 |
GPT-6 Luna | 90.0% | 94.1% | 90.0% | 77.6% | 95.0% | 88.8% | 4.9s | $0.10 / $0.50 |
GLM 5.3 Flash | 94.6% | 97.6% | 100% | 83.5% | 92.5% | 88.8% | 10.1s | $0.15 / $0.50 |
Gemini 3.7 Flash | 92.4% | 91.8% | 100% | 80.0% | 95.0% | 85.7% | 3.2s | $0.75 / $3.75 |
Claude Sonnet 5.5 | 93.0% | 92.9% | 100% | 82.4% | 92.5% | 88.8% | 4.8s | $2 / $10 |
Claude Opus 5.5 | 94.1% | 97.6% | 95.0% | 87.1% | 95.0% | 89.8% | 9.1s | $4 / $20 |
Single runs, exact-match grading. The decline suite has 20 tickets, so one ticket moves hallucination resistance by 5 points. Treat gaps of one or two tickets as ties.
Where Claude Haiku 5.5 is strong
Best at its price point. GPT-6 Luna is the only other model on the board at exactly $0.10 / $0.50. The two tie on answer accuracy (94.1%) and cited sources (77.6%), but Haiku 5.5 declined correctly on 95% of should-decline tickets against Luna's 90%, and that is the axis that decides whether a support bot is safe to leave unsupervised.
Fast, with a predictable tail. Median latency is 4.6 seconds and the 99th percentile is 9.5 seconds. GLM 5.3 Flash scores higher overall at a similar price, but its median is more than twice as slow and its p99 runs past 38 seconds, which customers notice in a live chat.
A real step up in restraint. On an earlier version of our decline suite, Claude Haiku 4.5 declined correctly only about 65% of the time. Haiku 5.5 reaches 95%, and the high-effort variant (adaptive thinking at high effort) declined on every should-decline ticket. For a small model, that is the difference between a cheap fallback you can trust and one you have to babysit.
Where it falls short
Ticket tagging. At 84.7% exact-match accuracy, Haiku 5.5 trails GPT-6 Luna (88.8%) and GLM 5.3 Flash (88.8%) at the same price. Its misses were spread across all three tag catalogs and split three ways: leaving a ticket untagged when a tag applied, tagging a ticket that should have stayed untagged, and picking a neighboring tag in the same family.
Cited sources. 77.6% of tickets were resolved and cited the expected article, versus 87.1% for Claude Opus 5.5 and up to 90.6% for Opus 5.5 at high effort. When a correct citation matters as much as a correct answer, the bigger models earn their price.
Hard intent routing. Haiku 5.5 passed 92.5% of intent-routing checks. Its misses were among the hardest cases in the suite: continuing a workflow the customer had already started, choosing between two near-identical billing intents, and recognizing a payment-return question as a configured intent. Claude Opus 5.5, GPT-6 Astra and Gemini 3.7 Flash miss some of the same checks, but the top models pass 97.5%.
The high-effort variant is not a free upgrade. Turning thinking effort up lifted hallucination resistance to 100% but lowered answer accuracy to 91.8% and raised median latency to 7.5 seconds. For live chat we would run Haiku 5.5 at low effort.
How IrisAgent uses it
IrisAgent does not bet on one model. Our multi-LLM engine picks a model per task from this board, and customers can choose the model they prefer. Claude Haiku 5.5 is a strong candidate wherever volume is high and latency matters: high-traffic chat fallbacks, first-pass answer drafting, and cost-sensitive batch work. For ticket tagging and citation-critical answers we still route to larger models. Every answer, whichever model writes it, goes through IrisAgent's grounding checks before it reaches a customer.
For the wider picture of how today's models compare on support work, see Best LLMs for customer support chatbots and how we measure accuracy.
See the full board
The Support Model Arena ranks every model we support by category, with latency and price next to quality. If you want to see how these models perform on your own tickets, book a demo.
Loading the form. Prefer email? Reach us at info@irisagent.comor call +1 617 249 3312.